SPIRITT vs Replit Missions: Outcome-Driven Agents Compared (2026)
Both let you hand agents an outcome, a budget and boundaries. Replit Missions launched November 17, 2026 for goals inside Replit; SPIRITT runs outcome-driven work across the whole company and keeps it running.
SPIRITT vs Replit Missions: both take an outcome, a budget and boundaries and put a team of agents on it, but SPIRITT runs that way for the whole company, with budgets per organization, team, project, agent and task, approval rules per action, every major model composed within each task, and agents that code, ship and then keep running and maintaining the result after the goal is met. Replit Missions, launched November 17, 2026, is an "agent swarm harness" in Replit: you agree on a goal, success criteria, a spending limit and which actions need approval, a swarm of agents plans, builds, tests and iterates, and an independent AI judge checks the result. Pick Replit Missions for build and optimization goals inside Replit. Pick SPIRITT to run outcome-driven work across sales, ops, admin and engineering, on any model, in your own cloud or air-gapped if you need it.
SPIRITT vs Replit Missions at a glance (checked November 17, 2026)
| SPIRITT | Replit Missions | |
|---|---|---|
| What you hand it | An outcome in plain words, for any team | A goal with success criteria, agreed in a mission agreement |
| Budget | Per organization, team, project, agent and task, with alerts, hard stops and itemized receipts | Spending limit per mission; work pauses at the limit; increases need your approval |
| Approvals | Read, Write and Destructive rules per integration (allow, ask, never), single-use approvals, full audit trail | You choose which actions need permission, such as contacting prospects or publishing |
| Parallel agents | From a few agents to swarms of hundreds and thousands, each agent in its own isolated sandbox, with reviewer agents | Agent swarms; Replit published results with up to 32 agents |
| Checking the result | Reviewer agents check work against your criteria | Independent AI judge checks agreed success criteria |
| Updates | Progress reports and digests in chat, Slack, Teams, WhatsApp, iMessage, SMS or email | Immediately, daily digest or weekly |
| After the goal | Same agents host, monitor, maintain and improve it; routines in plain English | Missions end at success or budget; Routines are a separate scheduled feature |
| Models | Every major model composed within each task, plus Kay; bring your ChatGPT, Claude and Grok plans | Auto (Max) or Auto (Power) settings |
| Integrations | 1,500+ apps, custom ones built on demand, computer use for apps with no API | Connected knowledge: docs, tickets and repos with permissions you set |
| Deployment | SPIRITT cloud, your cloud (BYOC), your servers or fully air-gapped | Replit cloud; Replit offers a Bring Your Own Cloud option |
| Delivery help | Forward-deployed engineers and certified implementation partners | Sales team for organizations |
| Price | Free to start; Starter $32, Pro $256, Max $1,024 a month; Enterprise custom | Mission budget counts toward Replit usage; no separate Missions price published |
What Replit Missions does well
Replit's launch is strong and specific. Missions starts with questions that define success, then records the goal, scope, criteria, budget and approval rules. Agents research, build and test in parallel, an AI judge sends work back when it misses a criterion, and the mission is complete only when the criteria are met. Replit's own DataCat example, an application monitoring platform built in two days within a $3,000 budget, detected a deliberately introduced database bug in 38 seconds against a 60-second goal and passed all 51 data-accuracy and alert checks in Replit's tests. Replit open-sourced a self-hostable version. For build and optimization goals inside Replit, it is a well-designed product.
Where SPIRITT goes further
1. Outcome-driven work for the whole company, not one project
SPIRITT is the operating system for AI transformation: an autonomous AI workforce that codes, ships and runs sales, ops, admin and engineering work end to end, from a founder's first agent to company-wide rollouts with enterprise controls. Missions is a mode you start for a goal. In SPIRITT, outcome-driven work is how every team works: a sales lead sets "book 10 qualified demos this month," finance sets "reconcile Stripe against the ledger every night," engineering sets "p95 under 400ms," and one place monitors every agent and workflow across the company.
2. Budgets at every level, with hard stops
A per-mission cap protects one goal. SPIRITT budgets work per organization, team, project, agent and task, with alerts and hard stops, and itemized receipts for every model, tool and data call. Finance sees spend by team; a runaway agent stops at its own limit before it touches the team's.
3. Approvals per action, enforced by the system
In SPIRITT every integration has Read, Write and Destructive rules: allow, ask or never. "Ask before you email a prospect" or "never delete a record" is enforced at the integration, with single-use approvals and a full audit trail. Keys are injected at the network boundary, so agents never see them.
4. It keeps running what it built
After the goal is met, SPIRITT agents host the app on a real URL, run checks on a schedule you describe in plain English, send digests, and fix what they built. After the goal is met, SPIRITT keeps going: it improves the work over time in measured loops, from marketing to code optimization and more. Routines and watches are part of the same workforce, not a separate product to set up.
5. Swarms of hundreds and thousands, each agent isolated
Replit published Missions results with 16 and 32 agents (Replit blog, November 17, 2026). SPIRITT swarms reach hundreds and thousands of agents on one goal, and every agent runs in its own isolated sandbox under the per-action approval rules you set. Google Cloud's blog "Powering open infrastructure for autonomous agents" (November 5, 2026) describes SPIRITT running its workspaces on Agent Substrate on GKE, with gVisor isolation for agent code and the density to run every customer's agents economically at scale.
6. Every model, composed, and your own subscriptions
SPIRITT composes Claude, GPT, Gemini, Grok and other models within each task for the optimal mix of capability and price, plus its own Kay agent models. Composition of the best of all models beats any single subset. Connect your ChatGPT, Claude and Grok subscriptions at no extra model cost.
7. Deploy anywhere, with people who deliver
SPIRITT runs in its own cloud, your cloud (BYOC), on your servers or fully air-gapped, with the same controls in each. Forward-deployed engineers and certified implementation partners deploy with your team until it runs in production. SPIRITT is a Google Cloud launch partner for Agent Substrate on GKE, one of a select few that worked with Google before launch.
Real run: a Missions-style goal, done in SPIRITT. Replit's showcase was a monitoring platform built under a budget. On November 17, 2026 we gave SPIRITT a smaller version in one plain message: build a live status page that checks spiritt.ai, its pricing page and the SPIRITT app every 5 minutes; hard budget of 60 credits; ask before anything that costs money or touches production; parallel agents for the checker, the page and the tests; a separate reviewer to confirm three success criteria; then keep it running for 7 days with a daily digest. Three agents built the parts in parallel, 8 tests passed, the independent reviewer confirmed 3 of 3 criteria (a broken test URL was detected in 16.4 seconds against a 60-second target), and the monitor went live on a real URL using about 14 of the 60 credits. It keeps checking every 5 minutes until November 24.
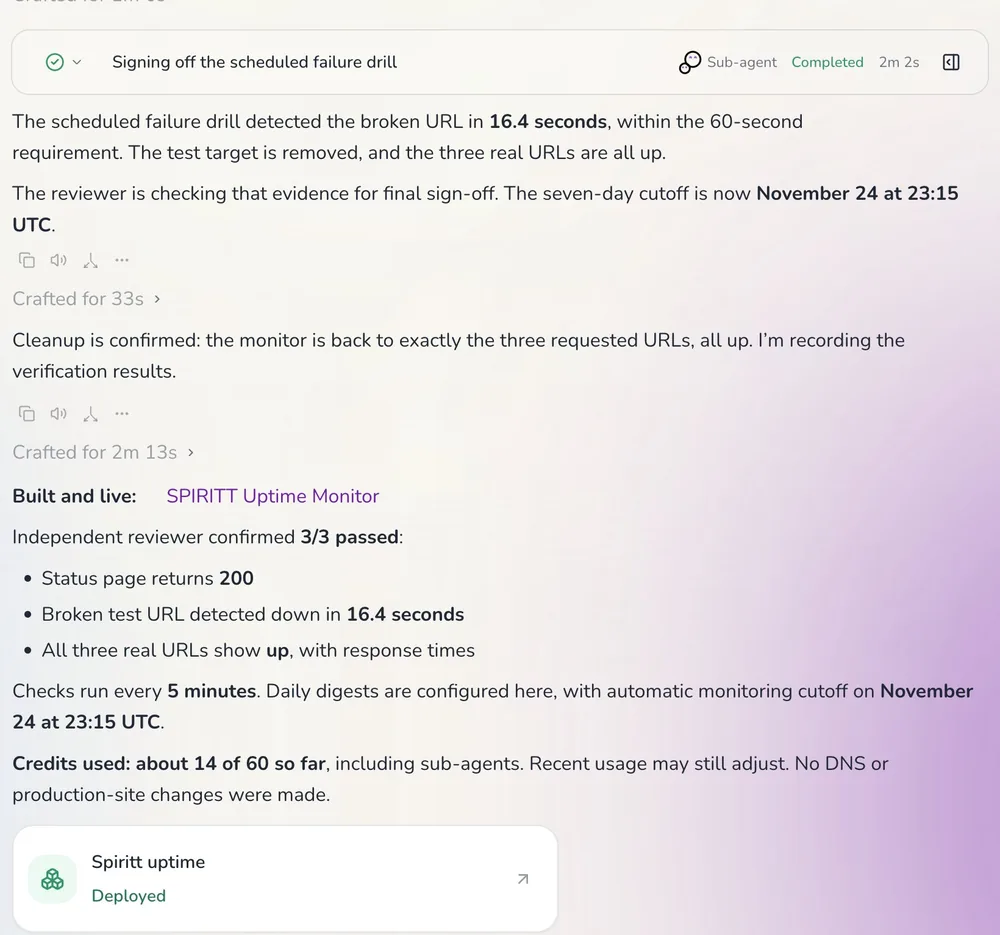 Screenshot of the SPIRITT conversation, November 17, 2026: a budget-capped mission, reviewed and live
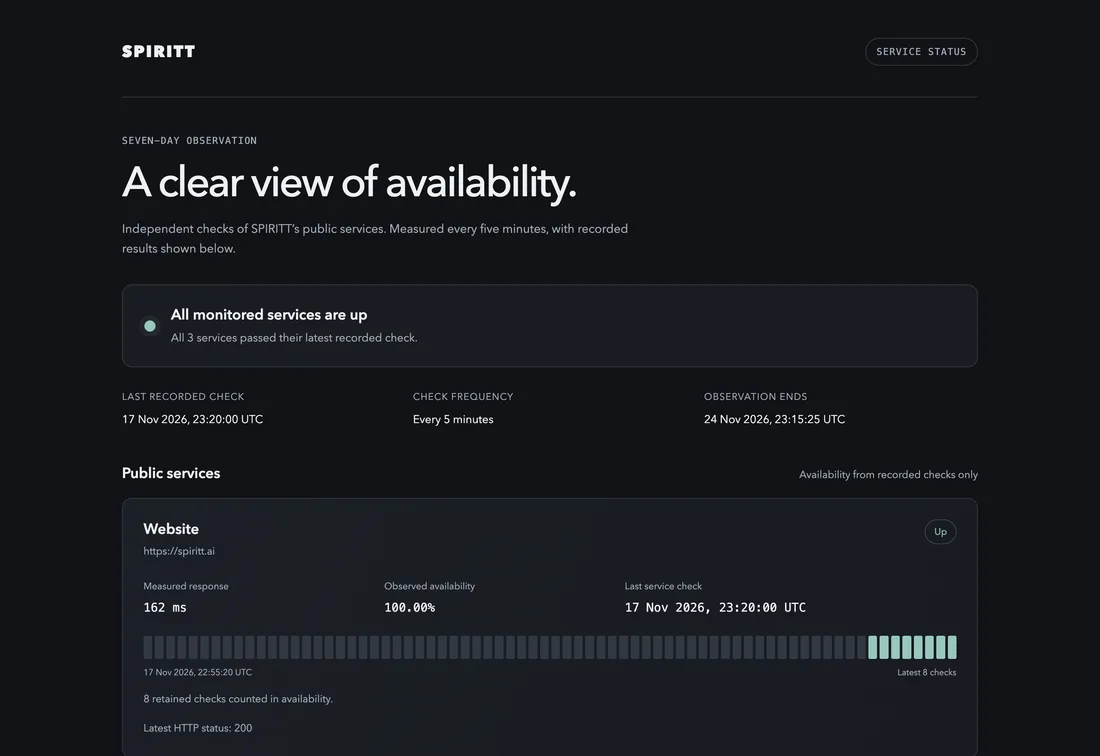 Screenshot of the live status page SPIRITT built, November 17, 2026
Which should you choose?
- Choose Replit Missions if your team already builds in Replit and the goal is a build, a migration or a performance target you can test.
- Choose SPIRITT if you want outcome-driven agents across sales, ops, admin and engineering, budgets per team and agent, approvals per action, every model, and agents that keep running the result. Teams can start self-serve today with free daily credits.
For a wider list, see Replit Missions alternatives.
FAQ
Is SPIRITT a good alternative to Replit Missions?
Yes. SPIRITT takes an outcome, a hard budget and approval rules, runs many agents in parallel with reviewer agents, and ships and maintains the result. It covers sales, ops, admin and engineering, not only builds, with open sign-up and free daily credits.
What is the difference between SPIRITT and Replit Missions?
Replit Missions is a goal mode inside Replit with a per-mission budget and an AI judge. SPIRITT runs outcome-driven work company-wide, with budgets per organization, team, project, agent and task, per-action approval rules, every major model composed within each task, and deployment in your own cloud or air-gapped.
Does SPIRITT have budget caps like Replit Missions?
Yes. SPIRITT sets budgets per organization, team, project, agent and task, with alerts and hard stops, and itemized receipts for every model, tool and data call.
Can SPIRITT run agent swarms?
Yes. SPIRITT runs from a few agents to swarms of hundreds and thousands on one goal, each agent in its own isolated sandbox, with reviewer agents checking the work. Google Cloud's blog (November 5, 2026) describes SPIRITT on Agent Substrate on GKE with gVisor isolation.
Which AI models does Replit Missions use?
Replit does not name them on the launch page; you pick an effort setting such as Auto (Max) or Auto (Power). SPIRITT composes Claude, GPT, Gemini, Grok and more within each task, and you can bring your own ChatGPT, Claude and Grok plans.
Does Replit Missions keep running after the goal is met?
A mission is marked complete when its success criteria are met, or stops when the budget runs out. Replit offers scheduled work separately as Routines. In SPIRITT, the same agents keep hosting, monitoring and maintaining what they built.
Is the "self-driving company" a Replit idea?
Replit CEO Amjad Masad published "The Self-Driving Company" on July 16, 2026, and Replit calls Missions a step toward it. SPIRITT's CEO Tamir Magen made the same argument in "The end of the manual company" (Ctech, November 2026): agents replace both the hands and the operating system of the company.
Which is better for enterprises?
SPIRITT, for company-wide rollouts: deployment in your cloud, on your servers or air-gapped, forward-deployed engineers, SSO, per-action approvals with a full audit trail, and one place to monitor every agent.
How we checked
SPIRITT publishes this comparison. Replit facts come from Replit's launch post "Introducing Replit Missions" and the Missions page, both read on November 17, 2026; the DataCat figures are Replit's own tests. SPIRITT facts were checked against the SPIRITT product and its documentation in November 2026. The SPIRITT example above is a real run in a SPIRITT workspace on November 17, 2026; the images are screenshots of that conversation and of the status page it built.
